The Real Cost of Custom LLM Integration in 2025 (And Why Most Pilots Fail)
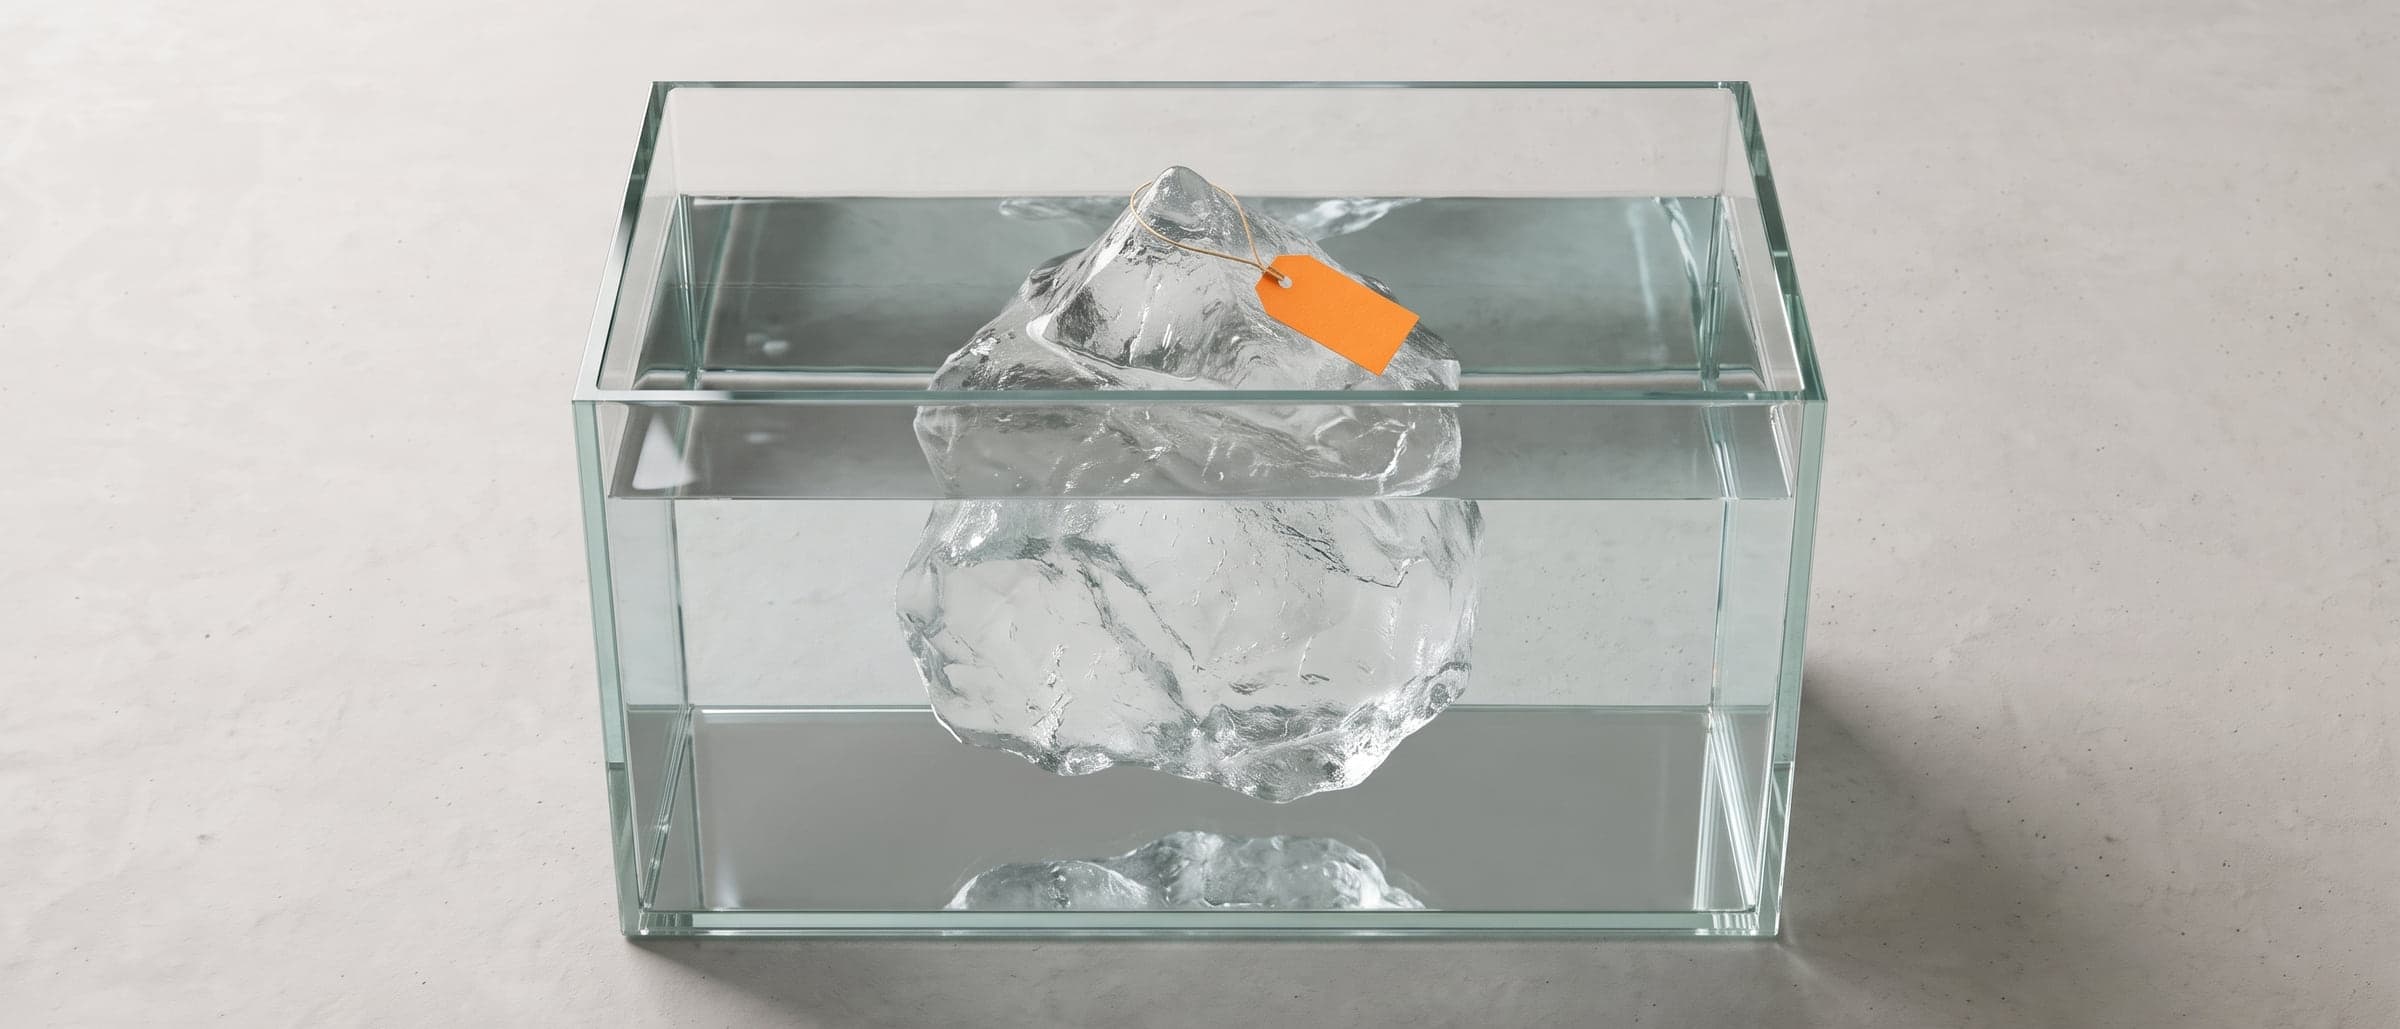
The quoted price of an LLM integration is rarely the total cost, because the model is only one part of a production system. Data preparation, integration engineering, monitoring and ongoing retraining make up the rest. Budget for the whole system, not for API access alone.
The initial budget approved for an enterprise AI initiative rarely covers the system that reaches production. Leadership teams allocate funds for API access and basic implementation, treating generative models as plug-and-play features. This misunderstanding of AI application development cost is where pilots stall: the pilot works, and the budget for the work production needs is not there.
The root cause is a failure to map the full cost surface of an AI deployment. Companies budget for the model, but they pay for the data pipeline, the evaluation framework, and the ongoing maintenance.
Why is the quoted price rarely the total cost?
When a vendor quotes a price for custom LLM integration for enterprise, they are often estimating the cost of connecting an API to a user interface. This is a demo. A production-ready AI system requires deterministic reliability from probabilistic models. Achieving that reliability demands rigorous engineering around the model itself.
Licensing and API fees are only one part of the total cost of ownership. Infrastructure, data preparation, and continuous monitoring make up the rest.
What are the cost layers of a production LLM system?
A resilient LLM integration consists of five distinct cost layers:
- Data Preparation
Preparing, cleaning and labeling data takes over 80% of the time spent on AI projects (Cognilytica, 2019). Vectorizing data, establishing access controls, and cleaning unstructured documents for Retrieval-Augmented Generation (RAG) is the most resource-intensive phase.
- Base Model Licensing and API Fees
The predictable, recurring cost of token usage. While base inference costs are dropping, high-volume transactional systems still generate significant monthly compute expenses.
- Integration Engineering
Writing the connective tissue. This includes prompt orchestration, API routing, fallbacks, and the logic required to ground the model in your enterprise data.
- MLOps and Monitoring
Models degrade. LLMs require observability to track drift, hallucination rates, and latency.
- Ongoing Retraining and Optimization
As your enterprise data changes, your embeddings and fine-tuned weights must be updated.
What is the gap between "demo-ready" and "production-ready"?
Pilots fail because the architecture that works for ten users testing a prototype shatters under concurrent enterprise load. A demo relies on pristine, static datasets. A production system must handle missing data, ambiguous user prompts, and API rate limits.
When a pilot transitions to production, the engineering focus shifts from "can the model answer this" to "what happens when the model hallucinates a compliance-violating response." Building guardrails, evaluation pipelines, and caching layers is what bridges the gap, and this work is almost never accounted for in pilot budgets.
- Licensing and API feesOnly one part of the total cost of ownership
- An API connected to a user interfaceThis is a demo
What the vendor quote often estimates
Almost never in the pilot budget
- Data preparationThe most resource-intensive phase
- Integration engineeringPrompt orchestration, API routing, fallbacks
- MLOps and monitoringDrift, hallucination rates and latency
- Ongoing retrainingEmbeddings and fine-tuned weights updated as data changes
- Guardrails, evaluation pipelines, cachingWhat bridges the gap to production
How do you scope LLM work?
Before committing budget to an AI integration, technical leaders must answer four pre-build questions:
- Where does the ground-truth data live, and is it accessible via API?
- What is the acceptable latency for a generated response?
- How will we quantitatively measure the accuracy of the model's output?
- What is the fallback mechanism when the model fails or returns an unsafe response?
If these questions remain unanswered, any budget estimation is a guess.
What is the value of a discovery phase?
A pilot writes code to see if an idea is possible. A Discovery Phase defines the exact architecture, data requirements, and financial model required to run the system at scale. Instead of building a disposable prototype, a Discovery Phase maps the data pipelines, produces an architecture brief, and provides a fixed-scope technical risk register.
Do not fund an integration based on the cost of the API. Audit your data readiness and map the production architecture before writing the first line of code.
Frequently Asked Questions
Why do AI pilots stall before production?
The pilot works, but the budget for production work is missing. A demo relies on clean, static data and a few testers. A production system must handle missing data, ambiguous prompts, concurrent load and API rate limits.
What does an LLM integration cost besides API fees?
Licensing and API fees are only one part of the total cost of ownership. Data preparation is the most resource-intensive part. Integration engineering, monitoring, and retraining as enterprise data changes make up the rest.
What should we answer before budgeting an AI integration?
Answer four questions. Where does the ground-truth data live, and is it reachable by API? What latency is acceptable? How will accuracy be measured? What is the fallback when the model fails? If these stay open, any estimate is a guess.
How does a discovery phase help with LLM work?
A pilot checks whether an idea is possible. A discovery phase defines the architecture, the data requirements and the financial model needed to run the system at scale. It maps the data pipelines and produces an architecture brief and a technical risk register.
Need help with a project like this?
Talk to our team about your specific situation. No sales pitch — just a conversation.
Talk to our team →Service: AI Development →